Accepted · IEEE BigData 2026
Cross-Modal Attention for Visual Question Answering
SDSU Data Science Lab, with Prof. Hajar Homayouni
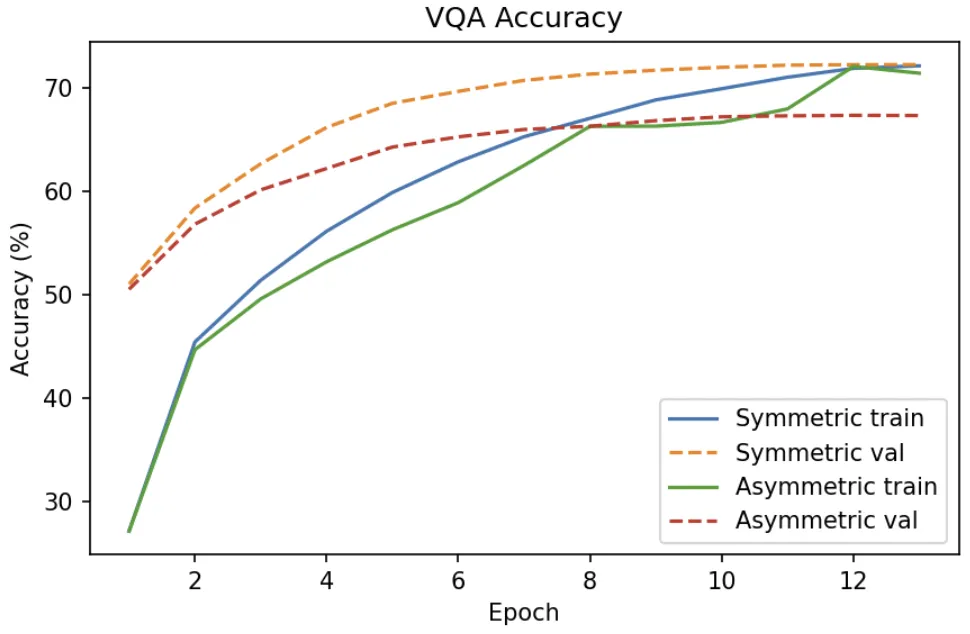
Can a model answer questions about an image better if vision and language attend to each other equally, or if one leads? I trained and compared both on VQA v2, then figured out why the asymmetric version overfit.
Read the full write-up →